↓ Skip to main content

What I've built and what I need: September 2026

The headline this month was turning the review skills into a scheduled, mostly unattended loop, and building the first instrument for where my session time actually goes. September came to 58 commits, over 180 files changed, and 14 new skills. The measurement points straight at what I need next: to stop babysitting sessions.

What I Have Been Working On
#

Turned reviewing others’ PRs into a scheduled, mostly unattended loop. review-requested-prs now fetches every PR waiting on me in one GraphQL query, runs discovery in parallel, sorts the queue by blocking depth, and skips any step already done for the current commit. It also recovers dropped team review requests from notifications, and a readiness light beside each PR marks when it can be auto-approved. The new assess-pr-risk scores a PR’s risk and confidence to decide how deep the review goes, using only evidence it gathers itself. The reverse direction, handling feedback on my own PRs, is triage-pr-feedback plus a FastAPI dashboard that groups and sorts incoming comments so I can mark each one implement, decline, or defer. handle-pr-reviewer-feedback owns that contract and triage just delegates. handle-failing-pr-ci lists my PRs’ CI status and fixes failures in parallel. review-pr-full chains the whole review, now starting with test-coverage analysis and committing its assets alongside the report.

Pushed verification earlier, into implementation. refactor-implementation runs between implementation and review to introduce only the abstractions the change needs. create-implementation now checks coverage and adds characterization tests before it modifies code. propagate-changes replaced backpropagate-sdlc and stopped being one-directional: it rewrites dependents and questions the premises they rely on. The repo’s own rules now say to get a working feature first, before any lint or type check.

Built an instrument for where session time goes. llm-sessions-analyzer reads the agentsview sessions.db archive read-only and attributes the wall-clock span between consecutive messages to a category: coding, testing, linting, formatting, build, exploration, research, git, delegation. It reports a stacked bar, a per-category table, and a timeline in the terminal or as a self-contained, sortable HTML report. The point is to find where the time actually goes: whether I am waiting on a specific tool most of the day (test suites run too widely or too often, lint and type checks that cost more than they save, builds whose artifacts never get used), or simply waiting on the model to generate.

Added visualization and writing skills. create-svg-image and create-mermaid-visualization split diagram work out of create-article, which now delegates to them, records the agent sessions that contributed to a piece, and requires direct statements over loose prose.

Grew the general-purpose skill set. setup-agent-machine/sync-agent-machine turn a directory into an indexed machine context. search-existing-issues, select-issue, trace-issues, create-discussion, and prune-merged-worktrees cover the issue lifecycle. slack-resolve-threads and improve-sessions mine Slack threads and past sessions for follow-ups and reusable lessons. create-skill authors a new skill from the best existing examples.

Made concise communication a shared rule instead of a per-skill habit. communication-guidelines is the single place every skill reads before it writes text on my behalf, from GitHub comments to Slack messages and email. It sets one principle (lead with the point, cut every sentence that does not change what the reader knows or does) and concrete length ceilings per surface. This matters more as more of the output is machine-written, since a language model’s natural failure mode is padding and repetition.

Taught an agent to read a day of Slack and report what was decided. extract-colleague-decisions searches Slack for the messages a set of colleagues authored in a day, reads the full threads behind them, and pulls out the decisions each person made, plus who supported them, citing a permalink for each and filtering out the chatter. The judgment is the point: telling a decision from an acknowledgement is a reading task, not a keyword match, and a small Jev classifier buckets each message to speed that judgment up.

Added a memory file so sessions stop relearning the same lessons. AGENTS.md carries the durable rules, but not the decisions, conventions, and gotchas discovered mid-session that the next one should inherit. MEMORY.md holds those, a global one for cross-project lessons and one per project for repository facts. Every session reads both at the start and writes back what it learns. It stays narrow on purpose: only what a future session cannot cheaply rediscover from the repo, kept concise and nothing a near-term commit would invalidate.

Tightened conventions and tooling. banned-terms.txt is now the single source of truth for banned terms, and report file naming was normalized across the review skills. The library was cleaned of Claude Code and .claude references and the old slack-cached name. create-pr gained reviewer context comments via ghx and design decisions in the description, and create-pr-description now diffs against the PR base with gh instead of Graphite.

What I Currently Need
#

I need to stop babysitting sessions. Most of my supervision time goes to steering a running agent and catching when the original prompt or context was wrong. That is the wrong place for my attention to be. What I want is a run that goes from prompt to end-to-end tested and verified on its own, and I do not have it yet.

I need proof that is easy to consume and that proves real behavior. The verification I need at the end is not the model asserting success. It is evidence a human can skim quickly that the thing we expected to work actually works, not that the agent hallucinated it working. Closing this gap is what makes the first one possible: I can walk away only when I trust the proof.

I need to go from one session at a time to many. I want to explore solving problems at scale as a learning exercise, mostly in software engineering projects, on the hunch that a generic framework is hiding there. The tooling (loops, the scheduler, the gates), the trust (relying on CI and review), and the process (how work is scoped and handed off) all feel like part of the blocker, and the sessions analyzer is my first attempt to see which one to attack first.

I need the review pipeline to stay fast as I lean on it more. review-requested-prs and the other review skills call the GitHub API directly, and I want to route them through ghx as a caching layer so repeated runs reuse cached issues, PRs, and comments instead of refetching them. That should cut API calls, raise the cache hit rate, and keep the hourly loop cheap enough to run without thinking about it.

See also
#

References
#

  • agents - the skill library where the review, implementation, and machine-context skills landed.
  • llm-sessions-analyzer - the tool built this month to measure where session time goes.
  • agentsview - the session archive llm-sessions-analyzer reads.
  • ghx - the GitHub CLI used across the review and feedback skills.

What I've built and what I need: August 2026

The headline this month was the product-side counterpart to the SDLC: a full PDLC skill set that carries an idea from discovery through measurement. August also realigned the verification skills around non-overlapping roles, added several new pipeline phases, and completed the ISO/IEC 25010 audit set. The month came to 61 commits, over 500 files changed, and 30 new skills.

What I Have Been Working On
#

Shipped the PDLC pipeline. This was last month’s open need, and it is now a self-contained product development lifecycle that wraps the engineering one. It covers discovery, validation, strategy, definition, launch, and measurement, with a proceed, pivot, or kill gate at every phase. PDLC is the only slash command; the 31 phase and cross-cutting sub-skills live under skills/pdlc/skills/ and the orchestrator loads them on demand. Artifacts live under .pdlc/, mirroring the .sdlc/ conventions: a shared reference file, a PDLC_DIR fallback, a state file, and a revision mode. Definition is the seam where the product work hands the settled what and why to SDLC. Two supporting skills came with it, create-roadmap and review-roadmap, and identify-feature-opportunities generates and ranks new ideas from the code surface.

Realigned the verification skills. validate-pr, verify-pr, and review-pr had overlapping mandates, so I split them into three questions: validate-pr asks whether the change builds the right product, verify-pr asks whether the product is built right using runtime proof, and review-pr judges code craft from static reading alone. The new review-requested-prs orchestrator runs the three across the PRs waiting on me and skips any step already done for the current commit using SHA markers. analyze-test-coverage became its own skill for reporting introduced tests, change coverage, and uncovered code, and review-pr-full chains the whole review into one pass.

Added SDLC phases and artifacts. A new validate-assumptions/review-assumption-validation phase collects the assumptions made during design, runs the cheapest experiment that could invalidate each risky one, and blocks implementation when an assumption fails. create-lifecycle/review-lifecycle document how a resource’s states, transitions, and retention change over time, and create-domain-model/review-domain-model became standalone so a domain can be understood before solutioning. create-project/review-project fill the context files for a new repository, and create-question/review-question record open questions with what they block. create-cli-design settles a feature’s command surface as a companion artifact to requirements. Generated artifacts carry a session_link so a reviewer can reopen the session that produced them, create-* auto-dispatches its review-* in a subagent, and outcome files list the artifacts a phase produced. A single HTML slide deck now presents the whole SDLC family.

Completed the ISO/IEC 25010 audit set. audit-sdlc is now the coordinator for the ISO/IEC 25010 quality model, with a mapping table from each characteristic to a skill. One skill now covers each remaining characteristic: functional suitability, performance efficiency, compatibility, usability, reliability, maintainability, and portability, alongside the existing security and observability audits.

Shipped general-purpose skills. devils-advocate argues the strongest case against an idea, plan, or decision before you commit. gh-stack manages stacked pull requests. post-slack-message posts or threads a Slack message. stakeholder-announcement drafts and posts infrastructure updates to stakeholder channels. agents-section-daily-refresh runs the daily curation of the agent-maintained section of this blog. sync-articles brings a batch of articles into conformance with the writing rules. handle-pr-author-feedback (renamed from handle-pr-feedback) verifies that an author’s new commits answer your review comments.

Gated GitHub writes and reworked tooling. A should-post-to-github script now gates every GitHub content write, and the PR skills default to not posting, so a comment or merge only happens when --post is passed. SDLC worktrees moved to /tmp/sdlc/<owner>/<repo>/<issue>, and ~/.sdlc/** and /tmp/sdlc/** are pre-approved in the agent CLI so unattended runs are not stopped by a prompt. Script references moved to ~/.agents/scripts/, the audit and find skills switched from grep to ripgrep, and CLAUDE.md and .claude were replaced by AGENTS.md and .agents across the library.

Tightened conventions. create-article now requires naming the referent rather than leaving a vague it, and the 2-5 link cap on its See also sections was removed.

What I Currently Need
#

I did not write this entry at the time, so I have no record of what I needed in August and am stating that plainly rather than reconstructing a list I cannot trust.

See also
#

References
#

  • agents - the skill library where the PDLC pipeline, the verification realignment, and the audit set landed.
  • ISO/IEC 25010 - the quality model the audit skills now map one to one.
  • ghx - the GitHub CLI used across the review and feedback skills.

The Duplicate Issue Was Written in Chinese

This morning I hit a bug and asked my agent to file an issue for it. It came back with a stop sign instead. The exact bug had already been reported, a few hours earlier, in Chinese. The agent did the one thing a decade of keyword search never did for me: it read a Chinese bug report and knew it was mine.

The Bug and the Request
#

The app is OpenChamber 2.0.0. In Settings, under Web Search, every option failed the same way. I picked a search provider, a toast appeared saying “Couldn’t save the web search choice.”, and the selection rolled back. A typical bug report.

I typed what I knew to my agent: create an issue, the web search choice cannot be saved, it happens when switching the search provider. Notice what I did not do. I did not search GitHub first, and I did not open the source. I gave the agent a half-formed report and moved on, expecting it to handle the rest.

The Skill That Fired
#

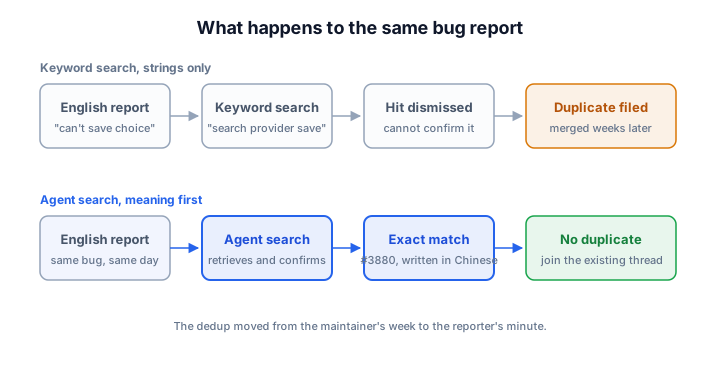
The skill my agent runs when I ask it to file an issue starts with one instruction: search for duplicates before any codebase investigation. It followed the skill without being asked. One grep matched my words to the app’s own UI strings, and then it ran three GitHub searches: “web search provider”, “search provider save”, and “websearch settings”. The first returned four unrelated issues, and the second returned the Chinese report as its top result. The queries were plain English, and the hit was still a Chinese report. The report’s body made the connection: the Chinese reporter had listed the failing endpoint, /api/config/websearch, and the frontend store, useWebSearchStore, and English identifiers like those match an English query no matter what language surrounds them. Retrieval was never the hard part, because code identifiers are already language-neutral. The agent opened the thread, read the Chinese, and did the translating after the hit, not before.

The Match
#

The match was issue #3880, titled “[Bug] v2.0.0 网页搜索选择无法保存,切换任何选项都会报错” (“the web search selection cannot be saved, switching any option shows an error”). It had been filed by a reporter I had never interacted with, and its prose was written entirely in Chinese. Same component, same toast, same rollback on every option. The Chinese reporter had even done their own careful investigation of their machine and listed the API calls involved.

The agent read the full report, compared it against mine, and concluded it was an exact match. Then it stopped. No new issue was filed, and it told me why in plain terms: a duplicate already exists, so it did not create one. It went one step further, checked the current source to confirm the bug was still present, and corrected a wrong guess in the existing thread’s comments.

Two paths after a bug report: a keyword search surfaces the Chinese report but the match cannot be confirmed and a duplicate gets filed, while an agent reads the hit, confirms it, and no duplicate exists

Why This Was New to Me
#

Duplicate detection was never bounded by retrieval, it was bounded by confirmation, and confirmation is reading. GitHub search matches strings, and it matches them in the issue body too. No English query matches the title 网页搜索选择无法保存, but the English identifiers in that report’s body match an English query fine. So a keyword search can surface a foreign-language report. What it cannot do is tell you the report is your bug, because judging the match means reading it. An English speaker looking at a Chinese-titled search result skips it or files anyway, and both paths end in a duplicate. I would have filed mine at exactly that step, not out of laziness, but because confirming the hit meant translating it by hand. The old workflow was not broken, it stopped one step short, and the step it stopped at was the language barrier.

The result in the old world is familiar to anyone who has maintained a project. The same bug arrives three times in three languages, a bilingual maintainer or a patient contributor eventually connects them, and the duplicates get merged weeks later, after the maintainers have already triaged each copy. The dedup always happened, but it happened on the maintainer’s time.

An LLM agent reads GitHub in any language it knows, Chinese as easily as English. The string search still does the retrieval, the reading does the confirmation, and both happen in the same minute of the same session. The dedup moves from the maintainer’s week to the reporter’s minute. The first useful thing my agent did that morning was refuse to do the work I asked for.

What to Do Next
#

If agents file issues for you, put duplicate-first at the top of the issue-filing skill, and make the language point explicit: tell the agent to treat translation as part of the search and to read candidate issues before dismissing them. A search that only matches your own language is a search that misses half the issues on GitHub. If your agent ever fails to catch a cross-language duplicate, check whether its search was string-bound.

If you maintain a project, expect the mirror image. Fewer copies of the same bug reach your queue, because the reporter’s agent catches them at filing time. The comments that still arrive can contain more than a symptom: an agent that finds an existing issue reads the thread, checks the current source, and can correct a wrong theory already in the thread, as mine did on #3880.

See also
#

References
#

  • OpenChamber issue #3880 - the Chinese-language report my agent matched, including the reporter’s own investigation of the failing save.

Micromanagement Doesn't Scale, for People or for Agents

Watch someone run an LLM agent for the first time and you will often see a familiar figure: the manager who initials every form. Management science named that figure decades ago, identified the failure, and defined the fix, and all of that work still applies now that the workers are agents. Micromanagement does not scale, and the worker it fails first is the agent.

The Same Behavior in Two Bodies
#

Micromanagement is the management pattern where the supervisor keeps decision rights over small steps instead of delegating outcomes and constraints. On a human team you recognize it instantly: the manager who approves every purchase, sits in every meeting, and rewrites every email before it ships. With agents you recognize it just as fast: the operator who approves every tool call, watches the output stream live, interrupts to argue about which file to read, and rewrites the plan twice before the first task finishes. The behaviors map one to one across the two worlds:

Micromanaged employee Micromanaged agent
Approves every expense, however small Approves every tool call
Sits in on every meeting Watches the output stream live
Rewrites every email before it ships Corrects the plan mid-run
Demands a check-in before each step Permission prompt on every command
Redoes the work at their own desk Aborts the run and does it by hand

The mapping is not a loose analogy. In both cases one person decides every small step before it happens, which is a statement about workflow structure, not about trust. Anything true of that workflow for humans stays true when the executor is a model.

The Arithmetic Kills It First
#

Management’s own term for the limit is span of control: the number of reports one manager can effectively supervise. The limit exists because a supervisor’s attention is a fixed budget, and every decision escalated to the supervisor spends some of that budget. Step-level delegation makes the team’s throughput equal to the supervisor’s evaluation throughput, since every step now waits on one person.

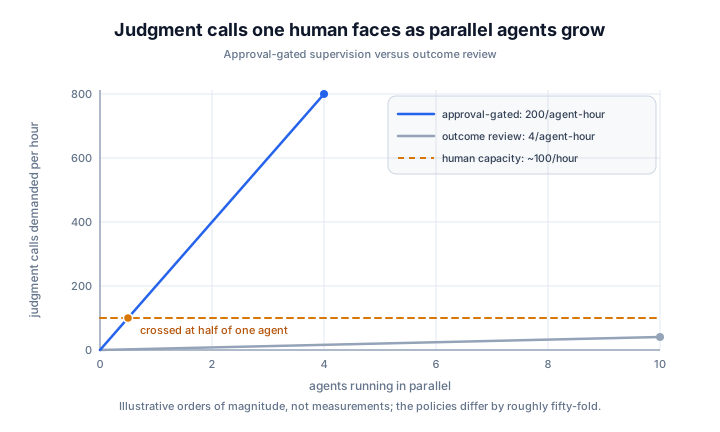
Agents make the arithmetic harsher. One agent in a normal working hour issues on the order of two hundred small decisions in my sessions: which file to open, which command to run, whether a result is good enough to build on. A human evaluates meaningfully at one or two decisions per minute, and the quality of those evaluations collapses long before the count runs out. Step-level supervision has a span of control below one agent: you cannot fully micromanage even a single one.

The two supervision styles diverge as soon as more than one agent runs:

Line chart: approval-gating demands roughly 200 judgment calls per agent-hour and crosses a human’s sustainable rate of about 100 per hour at half of one agent, while outcome review at 4 calls per agent-hour stays under the line even at ten parallel agents

The fatigue has a known endpoint. Once approval prompts become more than attention can handle, people stop reading the prompts and start clicking allow, and step-level supervision ends in the failure of approving without reading, which You Are the Bottleneck works out in queue-math form.

The economics fail alongside the arithmetic. An approval-gated agent runs at your evaluation speed, not the model’s, so you gained machine-speed execution and then limited it to human speed. The reason to hire an agent was to break the link between your attention and the work’s progress. Step-gating restores the link at every tool call.

It Also Corrodes What It Touches
#

Throughput is only the first cost. Micromanaged employees show the classic learned helplessness pattern: initiative collapses, problems stay hidden until they become impossible to hide, and judgment never develops because it never gets exercised. The manager pays too: never observing unassisted results, the manager cannot learn which reports handle which autonomy, so the manager’s distrust is not based on any evidence.

Agents repeat all of that, at higher frequency. Constant interruption disrupts the agent’s context, output quality drops, and the quality drop seems to justify even closer supervision. An operator hurt by mid-run questions starts specifying work in tiny increments, which guarantees the agent never runs long enough to produce a reviewable outcome. I caught myself doing exactly that after one bad run, restricting the agent until it could barely fetch a file, and the restriction felt like diligence the whole time. And the operator never builds the one calibration that matters: which task types, which models, and which risk levels can run alone. That calibration is the core skill of working with agents, and it can only form from watching end-to-end outcomes, the exact observations micromanagement prevents. Micromanagement keeps the one activity that does not scale, per-step evaluation, and neglects the two that do, the worker’s initiative and the supervisor’s calibration.

Why Smart People Do It Anyway
#

The justifications transfer intact. The worker is unproven: the new hire has no track record yet, and neither does the model you have never run on this task type. A past failure weighs on the decision: the intern who dropped a production table, the agent that once deleted the wrong directory. The credit asymmetry points the same way: catching a small error early is visible credit, while an outcome failure arrives late and is blamed on you, so close supervision is individually rational at every moment even though it is collectively ruinous.

The deepest cause is unfinished specification. When the supervisor can state what finished work looks like, steps are safe to delegate, because the check exists at the end. When the supervisor cannot state it, steps are the only thing left to inspect. Most micromanagement is not a trust problem with the report; it is a missing definition of done on the supervisor’s side.

What Scales in Both Worlds
#

The fix is decades old and applies without changes. Management by objectives says define the outcome and the constraints, then let the report choose the steps; for an agent, that is the specification and the acceptance criteria, ideally the tests. Verify at boundaries instead of continuously: milestones for people, the pull request for agents. Situational leadership says match supervision to demonstrated maturity, directing at first and delegating later. Agents deserve the same schedule: a new model on a new task type gets a tight loop, a proven pattern on a reversible task gets autonomy. Make autonomy affordable by scoping the blast radius: the unproven report gets the cheap, reversible work, and the agent gets the sandbox and the throwaway branch, so a failure costs a review cycle instead of an incident. Then reinvest the freed supervision hours into the specification, which is the act that multiplies rather than the act that caps.

Every item on that list was worked out on human teams, at human speeds, over decades of trial and error. Agents run the same experiment with faster workers and cheaper failures. A group of agents is the cheapest management simulator ever built, and its first lesson is the oldest one: govern outcomes, not steps.

But My People Are Not Experts
#

The fix in the last section rests on delegation, and the first objection is always the same: the team is not staffed with world experts, just regular developers, and regular developers make mistakes. Agents make more of them. The objection is legitimate, and it still does not justify step-level control, because the step-level trade fails on its own arithmetic.

Start with what delegation actually assumes. Delegation does not assume competence; it is the only way to observe it. Span of control and situational leadership were worked out for ordinary people, and ordinary people make mistakes. A supervisor who never lets a regular developer run alone never learns what that developer can handle, so the supervision level never moves off maximum, and the cycle continues despite good intentions.

Then move the safety mechanism from the person to the system. Step-watching is one way to catch mistakes, and the most expensive one ever tried. Boundaries catch them for a fraction of the cost: tests, small pull requests, staging. Blast-radius limits make the ones that slip through reversible: feature flags, sandbox, rollback. Every mistake that recurs becomes a gate, which catches that class forever without spending supervisor attention. The gates compound; the watching never does.

When a mistake lands anyway, recalibrate instead of escalating. Classify the failure: a one-off gets absorbed, a knowledge gap gets training, a pattern gets encoded as a check. Then autonomy returns to where it was, because the system now catches that class instead of you. Blanket step-control after every failure is how one bad day becomes a permanent surveillance regime.

Run the numbers and the objection collapses. Suppose step-watching catches twice as many mistakes as boundary review at fifty times the cost. The trade collapses your span of control and manufactures learned helplessness, which raises the mistake rate it was meant to suppress. Boundary review wins even when it is worse per mistake, because you can afford to run it forever and improve it every week. The imperfect model gets the same answer: its mistakes justify tests, a sandbox, small reversible tasks, and promoting every observed failure class into a gate, never approval on every tool call.

What to Do Next
#

Count your interventions on your next agent run. Past a handful, the interruptions mark missing specification, not a failing agent, and each one belongs in the next prompt or the skill file (Say It Once covers the conversion).

Write the acceptance criteria before you launch anything. Every impulse to watch closely converts into a check: the test you would have eyeballed, the log line you would have watched, the property of the diff you would have scanned for.

Give one low-stakes task a fully unsupervised run and grade the outcome. That grade is your first calibration point, and calibration points are how you widen autonomy without guilt.

Widen autonomy the way you would with a junior: task type by task type, on evidence, never on faith. The manager who cannot say which reports run alone has been micromanaging, and the operator who cannot say which tasks run alone is in the same place. Micromanagement is not a personality quirk, it is a supervision policy, and it stops working the moment the worker outproduces the supervisor’s judgment. Your agents reached that threshold on day one.

See also
#

References
#


How Much Attention Does This Pull Request Deserve?

Agents on my machines now review every pull request that asks for my attention, and they produce more review than I can read. That inverts the old problem: review used to be the scarce resource, and now the scarce resource is me. Most agentic reviews end in a single verdict, approved or rejected, and a single verdict throws away the two things I need in order to decide what to do next. Every agentic review should end with two scores, one for risk and one for confidence, because the question is never “is this pull request good” but “how much of my attention does it deserve”.

One verdict answers two different questions
#

When an agent review ends in a bare verdict, the verdict hides as much as it reveals. “Approved” can mean “I checked everything and found nothing”, or it can mean “I glanced at the diff and found nothing”, and those are very different claims. The fix is to split the judgment in two. Risk is a judgment about the change: how much damage it does if it is wrong, and how hard it is to undo. Confidence is a judgment about the review itself: how much of the risk judgment depends on evidence rather than on hope.

The two scores combine into a routing decision that neither score can give alone. A low-risk change with low confidence deserves a cheap second look, not a merge. A high-risk change with high confidence deserves a human reading the named risk drivers, not an automatic approval. And a high-risk change with low confidence is the dangerous case: the review is saying “this could hurt us, and I could not check much of it”, which deserves the strongest default.

Risk scores the change
#

My risk rubric, part of my agent skill library, scores seven factors, each Low, Medium, or High. Blast radius asks who calls the changed code, and whether the effect crosses package boundaries. Public interface asks whether the change breaks or removes a contract that other code depends on. Security sensitivity asks whether it touches authentication, authorization, cryptography, secrets, or input validation. Reversibility asks whether a revert undoes it, or whether it is a migration with no way back. Operational exposure asks whether the changed behavior sits on a hot path or behind a flag. Coverage gap asks whether tests cover the changed behavior. Churn asks how often the touched files changed in the past year, a cheap proxy for fragility.

Two rules keep the scores grounded. Every score above Low must cite file and line evidence, so a suspicion the agent did not confirm does not count. Every High score must name the concrete failure it makes expensive, and if the agent cannot name one, the score comes down to Medium with an explanation. The rollup is deliberately blunt: any High factor makes the change High risk, two or more Medium factors make it Medium, and everything else is Low. The bluntness is a feature, because the goal is not a precise number, it is a defensible triage call.

Confidence scores the evidence
#

Confidence is not the reviewer’s subjective impression of its own work, it is an audit of what the review could actually verify. My rubric counts six evidence points: a current validation report, a current verification report, runtime proof of its must-have criteria, a current code-craft review, a linked issue that states the intent, and a diff small enough to have been read in full. The caps matter as much as the points. No linked issue caps confidence at Medium, because there is nothing to check the change against. Verification that never ran the code caps confidence at Medium, because reading is not proof. A diff of a thousand lines or more caps confidence at Medium, and the report must say which areas were sampled rather than read.

The sentence I require most in the report names what would raise confidence. “Running the verification skill would add two points” turns the score from a vague judgment into a list of concrete actions. Because the scores are pinned to a commit, the assessment can be re-run when the evidence arrives, and the same pull request climbs from Low to High confidence without anyone re-arguing the risk. Confidence is not a number you state once, it is a number that should rise as evidence arrives.

The routing table turns scores into attention
#

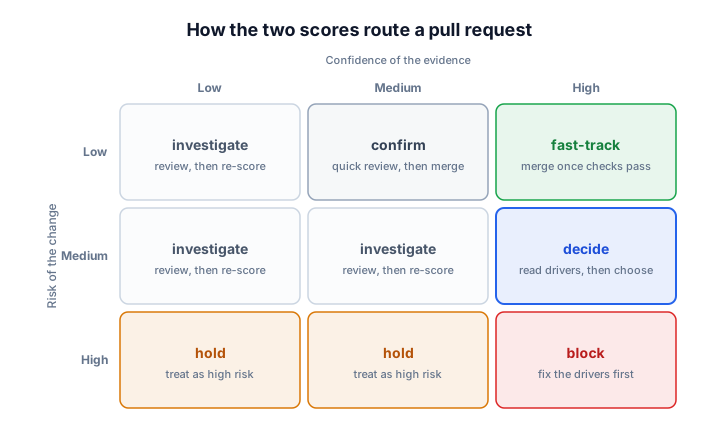
The two scores route each pull request to one of six verdicts: fast-track, confirm, investigate, decide, block, and hold.

A three by three grid with risk as rows and confidence as columns, where each cell names the next action: investigate, confirm, fast-track, decide, hold, or block

fast-track means I owe the change minutes: merge once checks pass. confirm means pay for one cheap review first, then fast-track. investigate means the evidence is too thin to route on, so run the full review pipeline and score again. decide is the interesting middle: the risk is Medium but the evidence is strong, so I read the named drivers and choose with findings in hand. block and hold are the expensive verdicts: the drivers must be resolved, or the change is treated as high risk until proven otherwise.

Each verdict names its next action, and that is what assigns a cost to attention. A queue of forty pull requests becomes a triage sheet: fast-tracks to clear immediately, a hold to schedule an evening for, and one decide to actually think about. The scores do not review the code, they decide where the scarce reviewer hours go.

The score routes the human, never the pipeline
#

The verdicts never gate the agent pipeline. A block verdict does not halt the chain of validation, verification, and craft review, and the chain never halts the risk assessment, which runs concurrently so the triage signal exists before the deep review finishes. The scores are advisory on purpose: the pipeline’s job is to produce evidence, the human’s job is to spend attention, and combining those jobs is how automation starts overruling people quietly. The verdict travels in a machine-readable marker pinned to the commit, so my orchestrator displays the risk and confidence columns without parsing a word of prose.

The same design is what makes the system scale. One script discovers every pull request across every repository that asks for my review, a fan-out gives one agent session to each pull request, and the orchestrator session collects a summary table for triage. The agents burn tokens, which are cheap, and I spend attention, which is not. Everything that can be mechanical is pushed to the machines, and what reaches me is a short list of decisions that cannot be.

What it looks like in practice
#

Three illustrative scenarios, the same ones I use as worked examples in the skill itself, show the range. A small internal fix, covered by tests, in files that change once a year: every risk factor Low, but no pipeline reports exist yet, so confidence is Medium and the verdict is confirm, one cheap review then merge. An authentication change with the full pipeline behind it: security sensitivity High, but runtime proof of every must-have criterion, so confidence is High and the verdict is block until the named session-invalidation gap is fixed. A 1200-line billing migration with no linked issue: reversibility and coverage both High, confidence Low and capped, so the verdict is hold, and the same pull request re-scores to decide once the full review completes. Same rubric, three very different amounts of reviewer time.

What to do next
#

If you run agent reviews, force every review to end with both scores, not one verdict. A five-minute rubric beats a bare approval: three risk factors and three evidence points are enough to start. Ban unverifiable confidence language: if the score cannot cite the evidence behind it, it is not a score. Make every verdict name its next action, so the queue reads as a budget rather than a pile. And track the mis-routings, because a fast-tracked pull request that burns your evening is calibration data, and the rubric should get stricter wherever it fails.

See also
#

References
#


My Agentic Schedule

Three skills run on my machines every hour, whether I am working or not. One prepares the review of every pull request waiting on me, one repairs the failing CI on my own pull requests, and one drafts my replies to reviewer comments. Each one is a skill file that fans out agents to do the reading, wired to a scheduler, and I have stopped doing the corresponding work by hand. The schedule is what turned them from tools I have to remember to use into infrastructure that works while I am away, and it reduced my part of the job to reading prepared options and deciding.

The trigger is the missing piece
#

An interactive agent session starts when I remember to start it. That ordering makes the work depend on me, and it makes me the one component in the system that can forget. Loops as Files makes the point generically: a skill with no trigger leaves the human as the trigger. These three loops are my way of making the scheduler the trigger instead of me.

The waiting is the other problem. An interactive session is synchronous: I trigger it, then I sit there while it reads, runs, and reports. A single analysis takes between 2 and 15 minutes depending on its complexity, and triggering them one at a time would spend my day waiting. The scheduled runs are asynchronous: they prepare the information a decision needs while I am away, and the decision is the only part left that happens with me in the room. One benefit of the workflows is that the information for a decision is ready when I sit down, instead of arriving only after I trigger an agent and wait for its output.

A schedule, rather than GitHub events, is a deliberate choice. Most pull requests I touch live in repositories I do not control, so I cannot install workflows, webhooks, or bots there. A local scheduler is the one trigger I own everywhere. Hourly is the cadence that works: fast enough that queues never build up overnight, slow enough that each run is cheap and usually finds nothing new to do. (The triage loop could safely run every fifteen minutes; hourly keeps the three aligned.)

The three hourly runs
#

All three run from my agent skill library, each as a markdown skill file plus a small deterministic discovery script. The skills are reusable by hand at any time; the schedule is just what keeps them from depending on my memory.

Preparing other people’s code reviews
#

The first run (review-requested-prs) prepares the pull requests waiting on my review, where I am the requested reviewer or already have. A script lists them all, then checks which review steps are already done for each pull request’s current commit, because every finished step leaves a report keyed to the commit SHA. The run dispatches only the stale steps, one agent per pull request, running up to five checks: risk assessment, test-coverage analysis, product validation, conformance verification, and code-craft review. The agents run in parallel, so a slow build on one pull request never delays the others. When I sit down to review, the verdicts and findings are already there, computed against the exact commit I am about to look at. The run does not approve anything; it does the reading so my part of the review starts at the decision.

Keeping my own CI green
#

The second run (handle-failing-pr-ci) lists my open pull requests and their combined CI status. Every pull request with failing checks gets its own agent in its own git worktree, so concurrent fixes never collide. The agent reads the failing logs, diagnoses the root cause, pushes the smallest fix that addresses it, and watches the checks settle. The autonomy is bounded: the agent reruns transient failures, returns an unclear root cause to me as a written diagnosis instead of a guess, and stops after two failed fix attempts. My pull requests arrive green, or they arrive with an explanation of why they are not.

Drafting my replies to reviewer comments
#

The third run (triage-pr-feedback) scans the pull requests I authored for reviewer comments still awaiting a response. For each pull request with new comments, a read-only agent checks out the pull request head and writes one recommendation file per comment: what the reviewer is asking, whether the claim holds against the code with file and line evidence, whether to implement or decline, how confident the analysis is, and a draft reply in my voice. State is one file per comment id, so a re-run only processes genuinely new feedback and never re-analyzes something I already decided. I read the resulting decision table, choose implement, decline, or defer, and only then does an executor skill post replies or push changes. Nothing reaches GitHub from this loop without my decision.

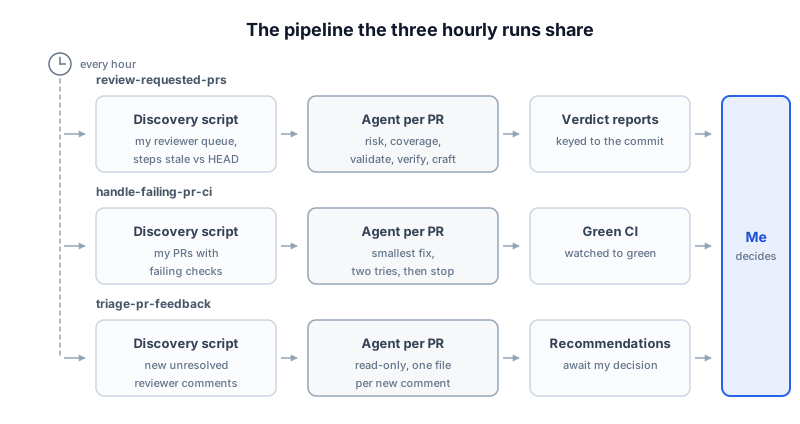
The pipeline they share
#

The three runs look different from the outside, but they are the same pipeline with three different sets of labels.

Flowchart of the shared hourly pipeline: a clock fans into three lanes, each running discovery script, one agent per pull request, and an output, all converging on a decision node labeled Me

Four properties make the pipeline safe to leave running.

Discovery is deterministic. A script, not a model, decides what needs work and what is already done. Discovery runs on every tick, so mistakes there compound, and judgment belongs in the per-item agents instead.

Work is fanned out one agent per pull request. Each pull request gets its own agent, its own worktree, and its own failure domain, so a slow or broken run stays contained.

State is stored in files, not in an agent’s memory. Verdict reports keyed to commit SHAs and one file per comment id mean a re-run is a no-op unless something changed. That is the property that keeps an hourly cadence inexpensive.

Write access is bounded and layered. The triage loop never writes to GitHub at all; it produces recommendation files. The review loop writes only step markers, so a later run knows which checks are done. The CI loop pushes, with pre-approval scoped to the smallest fix and explicit abort conditions that route back to me. Merging and replying stay mine.

What changed in practice
#

Review stopped being interrupt-driven: prepared material is ready before I start, and I pick the moment to start. The schedule is the batching You Are the Bottleneck argues for, minus the fixed timetable. CI failures stopped interrupting me because an agent picks them up within the hour, and I hear about one only when its diagnosis needs a human. Replying to reviewer comments became choosing between prepared options, which takes minutes instead of a context switch per thread.

The costs show up anyway. Skills drift as repositories and CI systems change under them, so the library needs tending. Correlated errors are possible: all three runs share one skill library, so one bad edit degrades all of them at once. And preparation is not judgment, which is why the risk-and-confidence routing from How Much Attention Does This Pull Request Deserve? matters once the agents produce more review than I can read. Every loop is designed so the taste decision (merge this, decline that) stays with me.

What to Do Next
#

Pick the queue you check most often; for most engineers that is pull requests or CI. Encode the discovery as a script: what needs work, and for each item, what is already done. Wrap the per-item work in a skill that one agent can run alone. Fan out one agent per item and write per-item state so re-runs are no-ops. Then schedule it, read-only first. Add write access last, scoped, with abort conditions that route back to you.

See also
#

References
#


Agentic Maintenance at Scale: Best Practices for a Fleet of Repositories

When agents do the maintenance, every repository you keep is a subscription to future work, and the subscription is paid in tokens. The instinct at scale is to automate harder, Dependabot on everything, a scheduled agent per repository, alerts routed to a bot. That instinct treats each repository as its own problem, and at fleet scale the fleet itself is the problem. Agentic maintenance is fleet management: deciding which repositories deserve work at all, deciding what work they deserve, and reusing every decision across as many repositories as it applies to.

Every repository is a standing work order
#

A repository that sits active in an organization is never neutral. Its Dependabot config opens version-bump pull requests on a schedule. Its security alerts accumulate. Any scheduled agent that sweeps the fleet reads all of it as a backlog. A repository that humans would quietly ignore, agents cannot, because an agent’s correct behavior when pointed at a repository full of signals is to act on them.

When I maintained five repositories, ignoring a dead one cost me a guilty glance once a month. With fifty, ignoring is no longer possible, because the automation keeps generating work regardless of whether anyone wants it. The cost is not per decision anymore, it is per repository per unit of time, whether or not anyone looks. Adding a repository to the fleet is adding a standing order for future work, and canceling that order is a maintenance task in itself.

Automation does not read intent
#

Dependabot has no strategy. It does not know that the library it wants to bump was superseded by another one, that the project is in maintenance mode, or that the product behind the repository was deprecated last quarter. It opens the pull request because a newer version exists, and it will keep opening them until someone makes it stop. The same is true for every scheduled agent: an agent that finds dependency alerts in a repository treats them as its work queue, because that is what it was told work looks like.

A dependency bump in a repository nobody is investing in is pure waste. It costs tokens to generate, CI minutes to validate, attention to review, and merge effort, and the value it delivers is zero because nobody is deploying the result. Multiply by the number of dead repositories and the number of updates per year, and the fleet generates unneeded pull requests continuously. Bots generate work at a fixed rate per repository, independent of that repository’s value, so the value decision has to be made somewhere else, by you, before the bots run.

Archiving is the off switch
#

The cheapest way to stop work on a repository is to archive it. An archived repository becomes read-only: issues, pull requests, and code can no longer be changed, which means Dependabot has nowhere to open its pull requests, alerts have nowhere to be fixed, and scheduled agents have no work to perform. The archive state is also a clear signal. GitHub describes it as marking a repository as no longer actively maintained, so bots, agents, and humans all read the same message: no future work here.

I used to think of archiving as an admission of failure, the end of a project. That framing is what keeps dead repositories alive, because nobody wants to declare a project finished. When I finally ran this pass over my own fleet, most of the repositories went straight to the archive, and the guilt I felt about them turned out to be a bug in my process, not a flaw in my priorities. The better framing is mechanical: archiving is the off switch for automated work, and a repository that will not receive maintenance should be switched off. A repository that is archived cannot waste tokens, and a repository that is merely neglected wastes them on schedule.

If the project matters again later, GitHub supports unarchiving, so the downside of a wrong archive decision is small. The downside of the opposite mistake, keeping a dead repository live, compounds every week the bots keep running.

The lifecycle has three tiers, and the automation should differ on each one:

flowchart LR
    A["Active<br/>full automation: Dependabot, scheduled agents, alerts"] -->|fewer users, less investment| B["Maintenance mode<br/>security updates only, batched and infrequent"]
    B -->|no users, no fixes planned| C["Archived<br/>read-only, no automation, zero token spend"]
    C -.->|a reason returns| A

Write the policy where the agents will read it
#

Not everything belongs in the archive, and not everything active deserves full service. A library with actual users but no development might deserve security bumps only, batched monthly. A template repository might deserve updates once a quarter. The tier matters only if the machines can read it.

The Dependabot config can encode part of the policy: version update schedules can be set to daily, weekly, or monthly, with per-dependency ignore rules for anything the policy declines. But the part that matters most to agents is in the repository’s agent instructions, the AGENTS.md layer, because that is the file agents actually obey. “Dependency pull requests: security alerts only, otherwise close with a pointer to the maintenance policy” is a sentence an agent can execute. No policy at all is also an instruction, and the instruction it gives is “everything here is worth maintaining”. An agent faced with an unannotated repository will invent a policy, and the invented policy is always maximum effort.

Sweep the portfolio, do not fight per-repository fires
#

The wrong way to run maintenance agents at scale is one agent per repository on a timer. That design multiplies cost by the repository count and makes the agent re-learn the same context on every run. The right granularity is the portfolio sweep: one scheduled run that walks every repository, collects the signals, and produces a ranked list of what deserves action this week.

The sweep output is a triage report, not a pile of pull requests. Agents then get dispatched only at the top of the list, where the value is, and everything ranked below the top gets a note instead of a token budget. A sweep also sees what per-repository agents cannot: the same change suggested everywhere.

The same suggestion everywhere is one change
#

Dependabot does not coordinate across repositories. It will open the same GitHub Actions version bump in thirty repositories, each one arriving as an independent pull request that looks like independent work. Read as a pile, that is thirty tasks. Read as a list, it is one upgrade. Aggregating the suggestions before acting on any of them is what turns the pile into a list, and the list is where the economies live.

The decision is the expensive part, and the decision does not often change per repository. Deciding whether actions/upload-artifact should move from v3 to v4 costs the same investigation whether you run it once or thirty times: what breaks, which workflows depend on the old behavior, what the migration needs. The per-repository work is the applying, and applying a decided change is mechanical, cheap, and fully delegable to an agent. So decide once, write the rationale once, and send the same answer to all thirty pull requests, applying the change in every repository and flagging the few that need an exception. The application happens once per repository either way, the saving comes from paying the decision once across all of them.

A suggestion that keeps returning is also a design signal. If every repository carries its own copy of the same workflow steps, every upstream action bump becomes thirty pull requests again next quarter, and the decision cost recurs with them. Move the repeated piece into a shared component, a reusable workflow or a composite action that lives in one repository and is called by all the others, and the next bump happens in one place by construction. The best fix for a maintenance task that repeats across the fleet is to stop repeating it, by giving the change exactly one place.

Measure maintenance in tokens
#

Human-scale maintenance was measured in hours, and hours were scarce enough to force triage on their own. Agentic maintenance is measured in tokens, and tokens are cheap enough that the waste goes unnoticed until the invoice arrives. So make the bill visible: track tokens spent per repository per month, alongside how much of that spend produced merged work.

The numbers feed the pruning loop. A repository that uses a large share of the budget while producing no merges is either misconfigured or dead, and either way the fix is the same conversation: what is this repository for, who uses it, and should it still be in the fleet. The token ledger is the portfolio review, and the portfolio review is where the fleet decisions come from: what to keep active, what to demote to maintenance, and what to archive.

What to Do Next
#

  1. List every repository you maintain and mark each one with the tier it deserves: active, maintenance mode, or archive.
  2. Archive everything in the third bucket today, and turn off its dependency automation before you do.
  3. For every repository that stays, write its maintenance policy into its agent instructions: what kinds of updates are wanted, how often, and what should be declined automatically.
  4. Replace per-repository scheduled agents with one portfolio sweep that produces a ranked list, and dispatch agents only at the top of the list.
  5. Aggregate the open suggestions across repositories before acting on any of them: group identical changes, make the decision once, and apply it everywhere with the same rationale.
  6. Centralize the pieces that repeat, such as shared workflows and composite actions, so the next change lands in one place.
  7. Track tokens per repository per month, and let the biggest spenders with the fewest merged outcomes lead the next round of archive decisions.

Maintenance at scale is not a stack of per-repository chores, it is the management of a fleet: admit work deliberately, decide once where the same change repeats, and keep the automation pointed at the repositories that matter.

See also
#

References
#


Nine Months of LLM Agents on Large Projects

Over the past nine months I have run LLM agents against the largest projects I have ever worked on alone: the open source tools I use and maintain daily, and the automated pipeline that publishes part of this blog. The models kept improving the whole time, and the improvements helped less than I expected. What actually helped was learning to handle four challenges: providing the right context, iterating through non-obvious design decisions, managing the scale of the work, and keeping artifacts consistent while decisions change. None of the four is about getting a model to write better code. All four decide whether the code the model writes turns into a finished project.

What the nine months covered
#

GitHub shows the scale better than my memory does: since January I have contributed 1,338 commits across 51 repositories, along with 66 pull requests and 181 issues. By mid September, 9 months in, the session counter read 3,400 sessions, 82,000 messages, and 6.8 billion tokens, 6.5 billion of them served from cache, spread across 63 projects and 33 models, on a path that had moved from Claude Sonnet 4.5 to GLM 5.3 Flash. The volume is not the point. The point is that the same four challenges appeared in every project, and how I answered them changed more than any model upgrade did.

Challenge 1: Providing the Right Context
#

Nine months ago my working assumption was that a capable agent would gather whatever it needed by exploring the repository. On a small project, that assumption holds. On a large one, it fails quietly: a session is generally scoped to a single location, one repository or directory, and a large project rarely fits inside one, so each session sees a narrow slice of the project, and cannot see the knowledge outside that slice. The cost showed up as steering time. I would launch a session, come back, and find it had built on a wrong assumption, then spend the next half hour correcting the session. Worse, the corrections sometimes left the written context inconsistent, one artifact updated while the artifacts that depend on it stayed stale, and later sessions inherited the contradiction as ground truth. On a large project, under-provisioned context does not just slow one session down, it causes errors in the sessions that follow.

What I do now is treat context provisioning as a phase with an exit condition, not a chore. Access first: every source the answers live in gets a way in and a pointer, which is the setup I described in Teach Your Agent Where Everything Lives. Then the map: which repositories exist, how they relate, where decisions live, written down so a cold session can orient in minutes. The exit condition: a cold session, dropped into the project with only its instructions file, can find every source it needs without asking me. I test it by giving the session a question whose answer I know is in one of the mapped sources, and provisioning is done when it comes back with the answer and the trail instead of a question. The underlying principle is the one I keep applying, that context quality dominates model choice. Every session I launch inherits the preparation, and every session I under-provision costs steering time.

Challenge 2: Iterating Through Non-Obvious Design Decisions
#

The decisions that cause large projects to fail are rarely the ones I can state up front. They are the non-obvious ones: how two modules should share a data format, what happens when a change is abandoned halfway through, whether a behavior belongs in a shared library or in the calling code. I cannot list those in a prompt, and an agent cannot discover them from the code alone, because half of them are not written down anywhere.

What I do now is iterate. Before any implementation session launches, I work with an agent to understand the current codebase and describe the changes we need to make, and we go back and forth until most open questions are resolved. The agent is a design partner, not a typist: it restates my description, catches the cases I overlooked, and proposes the alternatives I did not consider. The exit condition is simple: when the questions the implementing agent would ask have already been asked and answered, the design conversation is done. Answering a design question in conversation costs minutes. Answering it mid-implementation costs a stalled session, a wrong branch, or a refactor, and the stalls compound on every long run. This is the principle behind Say It Once, that every question an agent would ask mid-run should be answered before the run, applied one phase earlier: not just the standing rules, but the design itself.

Here is the loop as it runs today, from first contact with the codebase to the moment parallel sessions can safely start:

flowchart TD
    A[Explore the current codebase with an agent] --> B[Describe the change]
    B --> C{Open questions remain?}
    C -->|yes| D[Agent questions assumptions and proposes alternatives]
    D --> B
    C -->|no| E[Write decisions into the artifact tree]
    E --> F[Seed requirements and specs per feature]
    F --> G[Stand up the verification environment]
    G --> H[Partition the work and launch parallel sessions]

Challenge 3: Managing the Scale of the Work
#

A large project carries more work than one session can absorb, and more than I can supervise. On the most feature-heavy project I have run through my pipeline, the features outnumbered my attention within weeks: creating a directory per feature was cheap, walking each one through design personally was not. The answer is delegation and parallelism, but both have to be earned. Parallel sessions collide unless the work is partitioned along natural seams, and the seams only become visible through the design iteration of the previous section.

The preparation is what makes scale manageable. Each feature keeps its own artifact directory, seeded before any implementation session starts. Owning agents take features as far as they can and stop at the gates that need a human decision. Sessions get their own worktrees, so parallel work never conflicts. Tasks that share a file serialize; everything else runs in parallel. Parallelism is earned at partition time, not at spawn time. Spawning ten sessions on an unpartitioned codebase produces ten incomplete features and a merge conflict. Spawning ten sessions along the seams the design conversation exposed produces a project.

The other half of scale is me. With a dozen sessions running, I become the bottleneck unless decisions are batched and gates are explicit, which is the supervision problem I worked through in Managing Many Concurrent LLM Agent Sessions.

Challenge 4: Keeping Artifacts Consistent While Decisions Change
#

The final challenge never stops. On a project with dozens of interlocking features, decisions keep changing, and every change propagates. A revision to one feature’s specification forces updates in the requirements and plans of the features that consume what it produces. A session forked last week works from a snapshot that the sessions around it have already moved past.

Nine months ago I treated consistency as something to check at review time. Review time is too late: the stale artifacts have already fed other sessions by then. What I do now comes in two layers. Artifacts declare what they depend on, so the propagation has a map, and a propagation pass follows the map when an artifact changes, updating dependents or raising questions where a decision is needed. I worked out that mechanism in detail in What Needs Updating When Agents Do the Work. Verification environments catch whatever the map misses: an hour spent making the environment catch the inconsistency beats an hour reading diffs hoping to see it, which is the trade I laid out in My AI Workflow. Consistency on a large project is not a milestone you reach, it is a loop you run, and only a machine can run it at the frequency the project changes.

What to Do Next
#

  1. Before launching implementation, run the design loop with an agent until the open questions are resolved, and write the answers where the implementing sessions will read them.
  2. Treat context provisioning as a phase with an exit condition: access, map, pointers.
  3. Seed the artifact tree per feature before the first implementation session starts.
  4. Partition along the seams the design work exposed, isolate with worktrees, and serialize whatever shares a file.
  5. Add dependency declarations and a propagation pass so artifact consistency is maintained by loop, not by review.
  6. Watch your steering time: if you correct sessions more than you review them, the context was under-provisioned.

See also
#

References
#


What Needs Updating When Agents Do the Work

When an agent pushes a code change, the change itself is the fastest thing in the pipeline. The PR title and description written before the second revision, the review comments nobody answered, and the red CI run all become outdated and inconsistent with the code. Agentic work does not end when the code is written, it ends when a change has propagated through the graph of records in both directions.

The Push Is Never Final
#

In human-paced development, a push was a statement of completion. The author finished the work, wrote the PR title and description last, and pushed once. The PR title and description were accurate because they were written after the code settled.

Agentic development breaks that ordering. An agent pushes a first draft, receives feedback, addresses it, and pushes again. Then it rebases, fixes a failing test, and pushes again. Each push improves the code and invalidates the records describing the previous version. The diff updates itself on every push, the PR title and description do not.

That asymmetry is the whole problem. After three iterations, a pull request can contain correct code and inaccurate records describing it. The PR title and description explain a feature that no longer exists. The comments hold questions the final code already answers. The last CI run failed before the final fix landed, and nothing explains why the failure no longer matters. Nothing in the code is broken, and everything around the code is stale.

A Graph of Artifacts, Not a Checklist
#

These stale records look like a checklist: walk the pull request and fix each one. The checklist view fails because the records are not independent, each one was written from another. The artifacts around a change form a directed acyclic graph. The issue feeds the requirements, the requirements feed the specification, the specification feeds the code, and the code feeds the tests, the PR title and description, and the documentation, and no artifact feeds back into itself. Each artifact should declare what it depends on, because the declarations are the map that a propagation pass follows.

Here is the structure, with a change entering at the code node:

flowchart TD
    ISSUE[Issue] --> REQ[Requirements]
    REQ --> SPEC[Specification]
    SPEC --> CODE[Code]
    CODE --> CI[Tests and CI]
    CODE --> DESC[PR title and description]
    CODE --> DOCS[Documentation]
    SPEC --> DESC
    X([A change lands in one artifact]) -. enters .-> CODE
    ISSUE <-.-> REQ
    REQ <-.-> SPEC
    SPEC <-.-> CODE
    CODE <-.-> CI
    CODE <-.-> DESC
    CODE <-.-> DOCS
    SPEC <-.-> DESC

Solid arrows are declared dependencies: an artifact is built from the artifacts its solid arrows come from. Dotted double arrows are propagation, and they run along every edge in both directions. Downward, a changed artifact updates its dependents: the PR title and description must be rewritten, the documentation must describe the new behavior, and the test expectations must assert it. Upward, a changed artifact questions its premises: if the code had to deviate from the specification to work, the specification is now wrong, the requirements it satisfied are in doubt, and the issue behind them may be wrong too. No matter where the change lands, the two walks visit every artifact the declared edges connect.

Propagation has to run in both directions, because each direction catches a different kind of staleness. Downward-only propagation keeps the record aligned with the change while leaving the premises unexamined, which produces a consistent account of the wrong decision. Upward-only propagation questions everything and updates nothing. An agent runs both walks mechanically: it follows the declared edges, applies every update whose resolution follows from the change, and raises a question wherever two connected artifacts disagree in a way that admits more than one resolution.

A single forward pass is the ideal Say It Once argues for. The issue produces the requirements, the requirements produce the specification, the specification produces the code, and the code produces the rest, with every question answered before the next artifact starts. In most cases, though, the forward pass cannot complete in a single iteration, because some gaps become visible only when a downstream artifact is produced. Writing the code is how you learn the specification never said what happens when the input is empty. Writing the documentation is how you learn that nobody decided what the feature is called. Producing a downstream artifact is also a probe: it tests the artifacts before it, and every gap it finds sends the walk back upward.

The Update Loop
#

The loop below shows the graph operating at the pull request node, the place where every agent-authored change lands first. Automated review reads the diff and produces feedback. An agent addresses that feedback, with a human steering when judgment is needed. The agent then brings the pull request back in sync: it replies to the review comments, handles the CI failures, and updates the PR title and description if the latest push made them outdated. The documentation that describes the changed behavior is updated in the same pass. Then review runs again.

flowchart TD
    A([Code change pushed]) --> B[Automated review and CI run]
    B --> C{Feedback or failures?}
    C -->|none| M([Ready to merge])
    C -->|yes| D[Agent addresses the feedback]
    HUMAN[Human feedback] -. steers .-> D
    D -. raises questions .-> HUMAN
    D --> U[Agent brings the PR back in sync]
    U --> F[Replies to PR comments]
    U --> G[Handles CI failures]
    U --> I[Updates the outdated PR title and description]
    U --> DOCS[Updates the documentation]
    F --> B
    G --> B
    I --> B
    DOCS --> B

Every step in this loop has an owner, and the default owner is the agent. Assigning any step to a human by default re-serializes work the machine could finish in minutes, the same mistake made at pipeline scale when human review gates machine-rate output in Rethinking Code Review in the Age of LLMs. The update loop runs several times per pull request, so any step handled by hand multiplies by the number of iterations, not the number of pull requests.

The Three Update Jobs
#

At the pull request node of the graph, the propagation pass takes the form of three jobs. Documentation is a dependent of code too, and it is updated in the same pass, inside the same pull request as the code change.

Every comment gets a reply
#

An unanswered review comment is ambiguous. The reader cannot tell whether the agent missed it, disagreed with it, or resolved it silently in a later push. The agent should reply to every comment with what it changed and why, including an explicit “declined, because” when it rejects a suggestion. The reply is not politeness, it is what turns the thread into a record. A thread where every comment has an answer reads later as a decision log, and the human who scans it before merging reads conclusions instead of mysteries.

A CI failure is input, not a verdict
#

For a human author, a red build is a judgment to react to. For an agent, it is input to consume. The agent reads the failure, fixes the code, reruns the suite, and pushes. The loop continues without a human ever opening the log. Escalation stays reserved for the cases that need a decision: the same failure returning across pushes, a flaky test worth deleting, or a fix that changes behavior the specification did not authorize. A CI failure routed to a human queue is a decision the pipeline did not make.

The PR title and description follow the code
#

The PR description is written when the pull request opens, which means it describes draft one. The title goes stale the same way: it names the purpose the change opened with, and the purpose may have moved by the third revision. By the time the code merges, both can be documents about a version that no longer exists. The agent should rewrite the description after significant revisions, and update the title whenever the purpose of the change moved, so both always describe the current diff: what changed, why, and which suggestions were rejected and why. A PR title and description state what the diff does, and an agent that stops updating them is asking the reader to audit the diff to find out.

Where the Human Fits
#

The human feedback in the loop enters as steering, not as typing. The human does not write the replies, fix the builds, or reword the PR titles and descriptions. The human reviews the agent’s proposed resolutions and decides the contested suggestions. The human also ends disagreements, because an agent arguing with an automated reviewer can cycle forever, and only a human can decide the outcome. And the human answers what propagation cannot settle: an update either follows from the change or it does not, and when it does not, the upward walk stops and hands the human a decision instead of a diff. The human’s job is not to answer the comments, it is to decide what the answers mean. Attention spent typing replies is attention not spent steering, and steering is the part of the loop a machine cannot do, which is the same division of labor argued in The Acceptance Gap.

I run this loop on my own work. When I open one of my agent’s pull requests, the threads are answered, the failures are explained, and the PR title and description match the diff. The judgment calls are still mine, which is exactly where my attention is worth the most.

The division also has an upstream payoff. When review feedback keeps revealing the same misunderstanding, the fix is not a better reply, it is a better specification, and the human is the only one positioned to write it.

What to Do Next
#

  1. Make “reply to every review comment” a standing rule in your agent’s instructions, with an explicit declined-and-why format for rejected suggestions.
  2. Have an agent handle PR feedback asynchronously: when a piece of feedback lands, it is already addressed by the time you look, and your part is to immediately pick the action to take instead of manually triggering an agent to address it.
  3. Route CI failures to the agent before they reach a human, and escalate to you only on repeat failures or ambiguous fixes.
  4. Add a PR title and description refresh as a required step before every re-review request and before merging, so both always match the latest diff.
  5. Declare the dependencies between your artifacts: which issue a requirements document answers, which requirements a specification satisfies, which specification a change implements, which code a PR title and description describe. Propagation without a map is guesswork.
  6. After every change, run the propagation pass in both directions: update what depends on the change, and re-check what the change depends on.
  7. Watch the loop for livelock: when the same feedback returns twice, stop the agents and make the design call yourself.
  8. Audit the artifact graph occasionally: check whether every artifact still matches what it depends on, across issue, requirements, specification, code, tests, PR title and description, and documentation, and treat the mismatch rate as the measure of how much of this loop you are still running by hand.

See also
#

  • Rethinking Code Review in the Age of LLMs - the argument that verification moved from human reading to automated gates, the context that makes an agent-owned update loop necessary.
  • Abandoning Code Review in the Age of Agents - reason 11, that review comments no longer land anywhere, is the record half of the gap this loop closes.
  • Say It Once - the same principle applied around a run: answer the questions before the run, and answer every comment once, in the thread, after it.
  • Nine Months of LLM Agents on Large Projects - the project-scale version of the artifact graph, where artifacts declare dependencies and a propagation pass follows the map when one changes.
  • The Acceptance Gap - why acceptance, not review, is the gate between an agent and production, and where the human in this loop should spend attention.
  • My AI Workflow - where the skills and verification environments that automate this loop come from.

References
#


What a Senior Engineer Owes Their Reviewer

When a senior engineer opens a pull request, not reconstruct what it does. The standard is that everything that did not require a second person is already done before the review request goes out. CI is green, the diff is small and single-purpose, the description explains the change, the author has already read their own diff, and the proof that it works is in the PR. Anything less quietly converts review time into discovery time, and discovery is the most expensive way to use a reviewer.

The Standard Expectations
#

Setting aside the argument, here is what a reviewer can assume when a senior engineer opens a PR:

  • CI is green on the latest commit.
  • The diff does one thing; refactors and behavior changes live in their own PRs.
  • Stray logs, commented-out code, and unrelated reformatting are gone.
  • The author has read the full diff as if seeing it for the first time and annotated the lines that need context.
  • The description answers what changed, why, and how it was tested, and points at where to look closely and what is out of scope.
  • Proof that it works is in the PR: tests for new behavior, plus written manual verification when tests are impractical.
  • The requested reviewers own the subsystem you are touching, not whoever is idle.

Each of these assumptions a reviewer has to re-verify by hand is attention taken away from judging the change. When one of them breaks, the reasonable response is not a comment, it is returning the PR to draft.

The Cost of a Round Trip
#

The unit of waste in review is the round trip: the author requests review, the reviewer finds a gap, comments, and the change then sits in a queue until both people are free at the same time again. One round trip costs four context switches, two per side, plus a wait for the other person’s next open slot. The reviewer switches out of their own work to read the diff and back into it after commenting, and the author later switches out of their work to address the comment and back into it after pushing the fix. Because each switch means rebuilding the mental state you had before the interruption, a gap the author could have closed in minutes costs days of calendar time. Every expectation in the standard above exists to delete one class of round trip. A green build deletes the “your build is broken” loop, a single-purpose diff deletes the “split this up” loop, an annotated self-review deletes the “what is this line for” loop, and actual proof deletes the most expensive loop of all, “your tests do not cover this”, which costs a test rewrite plus a full second pass. Research on actual reviews backs the self-review obligation: in industrial code review, most comments ask for improvements and clarifications rather than catching actual defects (Bacchelli and Bird, 2013), and Google’s study of its own process treats small, fast changes as the mechanism that keeps review load sustainable (Sadowski et al., 2018). Review latency is mostly queueing, not judging, and the standard is how you keep the queue from growing.

The Handoff Contract
#

Review is a handoff, and a handoff has two sides. The author’s side is logistics: prove the change works, make it easy to read, explain why it exists. The reviewer’s side is judgment: design, correctness, and whether the code will still make sense in a year. When the author skips their half, the reviewer inherits it. A PR that forces the reviewer to reconstruct the intent is a PR that was opened too early.

The division of work looks like this:

flowchart LR
    subgraph Author["Author, before opening"]
        A1[CI green]
        A2[Self-review done]
        A3[Description written]
        A4[Proof of testing]
        A5[Small single-purpose diff]
    end
    A1 --> O[Open PR]
    A2 --> O
    A3 --> O
    A4 --> O
    A5 --> O
    O --> R["Reviewer: judgment only<br/>design, correctness, maintainability"]

Small, Single-Purpose Diffs
#

The highest-leverage habit is also the dullest one: keep the diff small. Google’s engineering practices make the case from experience, small changes get reviewed faster and more thoroughly, and reviewers miss fewer defects. Size is not the only variable though, purpose is. A senior engineer separates refactoring from behavior changes, because a diff that does two things forces the reviewer to review both at once and catch neither. If a PR needs a live walkthrough before anyone can understand it, that is usually a sign it should be several separate PRs.

There are legitimate exceptions, a generated-code migration or a mechanical rename can be large and still easy to review. What distinguishes a senior engineer is knowing which kind of large diff they have, and saying so in the description.

Self-Review Before Anyone Else Reviews
#

Before requesting review, the author reads their own diff on the same screen the reviewer will use, the Files Changed tab, end to end. This pass has two jobs. The first is debris removal: stray logs, commented-out code, leftover debugging, unrelated reformatting that inflates the diff. The second is annotation: leaving comments on the lines that need context, “this mirrors the logic above”, “this limit matches the upstream API”, so the reviewer does not have to ask.

Self-review is also where a senior engineer catches the embarrassing stuff, and catching it yourself is the whole point of being senior. Every defect the author removes before the review is a round trip that never happened.

A Description That Answers the Obvious Questions
#

The description exists so the reviewer never has to ask questions the author could have answered in writing. The questions are predictable:

  • What does this change do, and why is it needed?
  • How was it tested?
  • What should the reviewer look at most closely?
  • What is deliberately out of scope?

Screenshots for UI changes, before-and-after output for behavior changes, and a link to the ticket all belong here. The ticket link is a pointer, not a description. A reviewer who has to read the ticket to know what the PR does has been given work to do instead of a review request.

Proof That It Works
#

The author’s job is to demonstrate the change works, not to believe it works. That means tests for new behavior, updated tests for changed behavior, and a written note on manual verification when tests are impractical (“ran the migration against a copy of staging, 4.2M rows, 90 seconds”). I put this in the description under “How I tested this”. The reviewer’s job is then to audit the proof: are the tests actual assertions or tautologies, do they cover the failure modes, is the manual claim plausible. An author who ships “seems to work” is asking the reviewer to do QA on a hunch, and most reviewers respond to that with a request for changes.

After You Open It
#

The standard does not end when the PR is opened. Watch CI and fix failures immediately; a PR with a red build is blocking a reviewer for nothing. Respond to comments within a day, even if the answer is “I’ll get to this Thursday”. Push fixes as commits so the reviewer can see what changed since their last pass, and say when the PR is ready for a re-review. When a comment thread passes about twenty back-and-forths, take it to a call and write the conclusion back into the PR. And when you disagree with a reviewer, either convince them, accept the change, or escalate; a senior engineer does not leave a PR stuck in a stalemate.

When You Cannot Meet the Standard Yet
#

The standard has legitimate exceptions, and seniority shows in running the exception protocol instead of quietly lowering the standard. Sometimes the approach is still unsettled, sometimes a change cannot be split cleanly, and sometimes you need early feedback to avoid building the wrong thing for a week. Each case has a protocol that keeps discovery on the author’s side of the handoff:

  • The approach is unsettled: settle it in a short design note or issue before writing code; a paragraph of prose resolves an approach faster than three rounds of review comments on code that will be thrown away.
  • You need early feedback: open the PR as a draft and name the exact question and the lines that answer it, for example “design feedback on the cache interface only, ignore the internals”.
  • The diff is unavoidably large: stack it, base each PR on the previous one, and keep every PR in the stack single-purpose so the reviewer can approve them in order.
flowchart TD
    Q{"Cannot meet the<br/>standard yet?"} -->|"Approach unsettled"| D["Design note or issue<br/>settle the approach first"]
    Q -->|"Early feedback needed"| E["Draft PR<br/>name the question and the lines to read"]
    Q -->|"Diff too large"| S["Stacked PRs<br/>each one single-purpose"]
    D --> R["Then open a PR<br/>that meets the standard"]
    E --> R
    S --> R

The difference between a draft and a premature PR is that the draft tells the reviewer what to look at, and what to ignore. “Is this the right approach?” is a question a reviewer can answer in five minutes. “What is this PR doing?” is a request to do the author’s work.

Make the Standard the Default
#

None of the seven expectations should depend on memory, because memory fails on exactly the days the standard matters most, the rushed ones. Encode it once and let the system enforce it:

  • A PR template with the four description questions already written out.
  • Format and lint gates in CI, so reformatting changes never reach a human-reviewed diff.
  • A draft-first habit: every PR starts as a draft and only moves to ready when the checklist passes.
  • Reviewer assignment by code ownership, so requests route to the subsystem’s owners instead of whoever is idle.

There is a quieter reason a senior engineer maintains this standard. A senior engineer’s PRs are the template the rest of the team copies, because people calibrate to what actually gets merged, not to what a wiki says. The first time the team watches its most senior member ship a rushed PR to quick approvals, the written standard stops being followed. If you want to change how a team reviews, change what its most visible engineers ship.

What to Do Next
#

Before you click “Request review” next time, walk the seven expectations in the list above one last time, in order. Then go a step further and audit your last three merged PRs: find the expectation you break most often under deadline pressure, and encode it once, as a template line, a CI gate, or a personal checklist item. A standard you re-derive from memory every time will weaken; a standard encoded in the system keeps working even in your worst week. None of this requires talent. It is the difference between treating review as a service you consume and a contract you enter, and seniority is mostly about honoring that contract.

See also
#